 |
1.11
User Documentation for MADlib
|


|
|
1.11
User Documentation for MADlib
|
|
A marginal effect (ME) or partial effect measures the effect on the conditional mean of  for a change in one of the regressors, say
 . In the linear regression model, the ME equals the relevant slope coefficient, greatly simplifying analysis. For nonlinear models, specialized algorithms are required for calculating ME. The marginal effect computed is the average of the marginal effect at every data point present in the source table.
MADlib provides marginal effects regression functions for linear, logistic and multinomial logistic regressions.
margins( model_table,
         output_table,
         x_design,
         source_table,
         marginal_vars
       )
Arguments | variables | INTEGER[]. The indices of the basis variables. |
|---|---|
| margins | DOUBLE PRECISION[]. The marginal effects. |
| std_err | DOUBLE PRECISION[]. An array of the standard errors, computed using the delta method. |
| z_stats | DOUBLE PRECISION[]. An array of the z-stats of the marginal effects. |
| p_values | DOUBLE PRECISION[]. An array of the Wald p-values of the marginal effects. |
VARCHAR, default: NULL. The design of independent variables, necessary only if interaction term or indicator (categorical) terms are present. This parameter is necessary since the independent variables in the underlying regression is not parsed to extract the relationship between variables.
Example: The independent_varname in the regression method can be specified in either of the following ways:
‘array[1, color_blue, color_green, gender_female, gpa, gpa^2, gender_female*gpa, gender_female*gpa^2, weight]’ ‘x’ In the second version, the column x is an array containing data identical to that expressed in the first version, computed in a prior data preparation step. Supply an x_design argument to the margins() function in the following way:
‘1, i.color_blue.color, i.color_green.color, i.gender_female, gpa, gpa^2, gender_female*gpa, gender_female*gpa^2, weight’The variable names ('gpa', 'weight', ...), referred to here as identifiers, should be unique for each basis variable and need not be the same as the original variable name in independent_varname. They should, however, be in the same order as the corresponding variables in independent_varname. The length of x_design is expected to be the same as the length of independent_varname. Each identifier name can contain only alphanumeric characters and the underscore.
Indicator (dummy) variables are prefixed with an 'i.' (This is only necessary for the basis term; it is not needed in the interaction terms.) Indicator variables that are obtained from the same categorical variable (for example, 'color_blue' and 'color_green') need to have a common and unique suffix (for example, '.color'). The '.' is used to add the prefix and suffix. If a reference indicator variable is present, it should contain the prefix 'ir.'.
An identifier may contain alphanumeric characters and underscores. To include other characters, the string must be double-quoted. Escape-characters are not currently supported.
VARCHAR, default: NULL. Name of the data table to apply marginal effects on. If not provided or NULL then the marginal effects are computed on the training table.
margins_logregr( source_table,
                 output_table,
                 dependent_variable,
                 independent_variable,
                 grouping_cols,
                 marginal_vars,
                 max_iter,
                 optimizer,
                 tolerance,
                 verbose_mode
               )
Arguments
VARCHAR. The name of the result table. The output table has the following columns.
| margins | DOUBLE PRECISION[]. The marginal effects. |
|---|---|
| std_err | DOUBLE PRECISION[]. An array of the standard errors, using the delta method. |
| z_stats | DOUBLE PRECISION[]. An array of the z-stats of the marginal effects. |
| p_values | DOUBLE PRECISION[]. An array of the Wald p-values of the marginal effects. |
A summary table named <output_table>_summary is also created, which is the same as the summary table created by logregr_train() function. Refer to the documentation for logistic regression for details.
margins_mlogregr( source_table,
                  out_table,
                  dependent_varname,
                  independent_varname,
                  ref_category,
                  grouping_cols,
                  marginal_vars,
                  optimizer_params,
                  verbose_mode
                )
Arguments
VARCHAR. The name of result table. The output table has the following columns.
| category | The category. |
|---|---|
| ref_category | The refererence category used for modeling. |
| margins | DOUBLE PRECISION[]. The marginal effects. |
| std_err | DOUBLE PRECISION[]. An array of the standard errors, using the delta method. |
| z_stats | DOUBLE PRECISION[]. An array of the z-stats of the marginal effects. |
| p_values | DOUBLE PRECISION[]. An array of the Wald p-values of the marginal effects. |
A summary table named <out_table>_summary is also created, which is the same as the summary table created by mlogregr_train() function. Refer to the documentation for multinomial logistic regression for details.
SELECT madlib.margins();
patients dataset from the Logistic Regression examples. SELECT * FROM patients;Result:
 id | second_attack | treatment | trait_anxiety
 ---+---------------+-----------+---------------
  1 |             1 |         1 |            70
  3 |             1 |         1 |            50
  5 |             1 |         0 |            40
  7 |             1 |         0 |            75
  9 |             1 |         0 |            70
 11 |             0 |         1 |            65
 13 |             0 |         1 |            45
 15 |             0 |         1 |            40
 17 |             0 |         0 |            55
 19 |             0 |         0 |            50
  2 |             1 |         1 |            80
  4 |             1 |         0 |            60
  6 |             1 |         0 |            65
  8 |             1 |         0 |            80
 10 |             1 |         0 |            60
 12 |             0 |         1 |            50
 14 |             0 |         1 |            35
 16 |             0 |         1 |            50
 18 |             0 |         0 |            45
 20 |             0 |         0 |            60
DROP TABLE IF EXISTS model_table;
DROP TABLE IF EXISTS model_table_summary;
DROP TABLE IF EXISTS margins_table;
SELECT madlib.logregr_train( 'patients',
                             'model_table',
                             'second_attack',
                             'ARRAY[1, treatment, trait_anxiety, treatment^2, treatment * trait_anxiety]'
                           );
SELECT madlib.margins( 'model_table',
                       'margins_table',
                       'intercept, treatment, trait_anxiety, treatment^2, treatment*trait_anxiety',
                       NULL,
                       NULL
                     );
\x ON
SELECT * FROM margins_table;
Result:
variables | {intercept, treatment, trait_anxiety}
margins   | {-0.876046514609573,-0.0648833521465306,0.0177196513589633}
std_err   | {0.551714275062467,0.373592457067442,0.00458001207971933}
z_stats   | {-1.58786269307674,-0.173674149247659,3.86890930646828}
p_values  | {0.112317391159946,0.862121554662231,0.000109323294026272}
DROP TABLE IF EXISTS result_table;
SELECT madlib.margins( 'model_table',
                       'result_table',
                       'i, tre, tra, tre^2, tre*tra',
                       NULL,
                       'tre'
                     );
SELECT * FROM result_table;
Result:
-[ RECORD 1 ]-------------------
variables | {tre}
margins   | {-0.110453283517281}
std_err   | {0.228981529064089}
z_stats   | {-0.482367656329023}
p_values  | {0.629544793219806}
\x OFF
SELECT * FROM test3;
Result:
 feat1 | feat2 | cat
-------+-------+-----
     2 |    33 |   0
     2 |    31 |   1
     2 |    36 |   1
     2 |    31 |   1
     2 |    41 |   1
     2 |    37 |   1
     2 |    44 |   1
     2 |    46 |   1
     2 |    46 |   2
     2 |    39 |   0
     2 |    44 |   1
     2 |    44 |   0
     2 |    67 |   2
     2 |    59 |   2
     2 |    59 |   0
...
DROP TABLE IF EXISTS model_table;
DROP TABLE IF EXISTS model_table_summary;
DROP TABLE IF EXISTS result_table;
SELECT madlib.mlogregr_train('test3', 'model_table', 'cat',
                             'ARRAY[1, feat1, feat2, feat1*feat2]',
                             0);
SELECT madlib.margins('model_table',
                      'result_table',
                      'intercept, feat1, feat2, feat1*feat2');
\x ON
SELECT * FROM result_table;
Result:
-[ RECORD 1 ]+-------------------------------------------------------------
category     | 1
ref_category | 0
variables    | {intercept,feat1,feat2}
margins      | {2.38176571752675,-0.0545733108729351,-0.0147264917310351}
std_err      | {0.851299967007829,0.0697049196489632,0.00374946341567828}
z_stats      | {2.79779843748643,-0.782919070099622,-3.92762646235104}
p_values     | {0.00514522099923651,0.43367463815468,8.57883141882439e-05}
-[ RECORD 2 ]+-------------------------------------------------------------
category     | 2
ref_category | 0
variables    | {intercept,feat1,feat2}
margins      | {-1.99279068434949,0.0922540608068343,0.0168049205501686}
std_err      | {0.742790306495022,0.0690712705200096,0.00202015384479213}
z_stats      | {-2.68284422524683,1.33563578767686,8.31863404536785}
p_values     | {0.00729989838349161,0.181668346802398,8.89828265128986e-17}
The standard approach to modeling dichotomous/binary variables (so  ) is to estimate a generalized linear model under the assumption that follows some form of Bernoulli distribution. Thus the expected value of becomes,

where G is the specified binomial distribution. For logistic regression, the function  represents the inverse logit function.
In logistic regression:
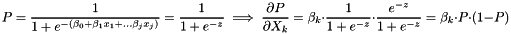
There are several methods for calculating the marginal effects for dichotomous dependent variables. This package uses the average of the marginal effects at every sample observation.
This is calculated as follows:
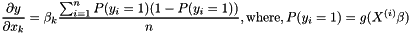
We use the delta method for calculating standard errors on the marginal effects.
[1] mfx function in STATA: http://www.stata.com/help.cgi?mfx_option
File marginal.sql_in documenting the SQL functions.
 1.8.13